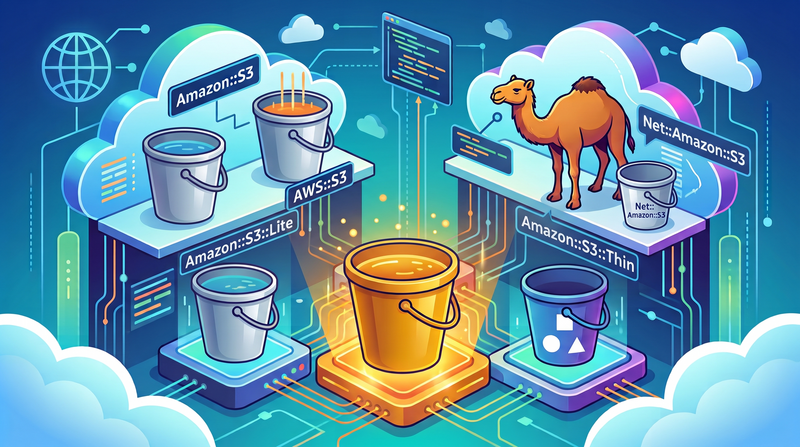
..and the difference between API completeness and a useful Perl interface
Today I am releasing version 2.1.0 of Amazon::S3.
This is the largest update to Amazon::S3 in some time. It adds modern S3 checksum support, including CRC64NVME; checksum verification on downloads; improved multipart upload handling; better S3 error reporting; fixes and additional tests for the dynamically generated BucketV2 API; substantially rewritten documentation; and a simpler build system.
It also began with a bug report that, for a while, made me wonder whether adopting this module had been a mistake.
My initial thought was to accept the PR, take out the offending code and move on.
Instead, the module needed a few other fixes, including some I had
already made but never released. I was also dissatisfied with the
autoconf based build system, so it was time to address that as well.
All of those things pushed Amazon::S3 maintenance to the top of my queue.
Then the deeper investigation exposed a fundamental misunderstanding about ETags and checksums that had been baked into the module years ago.
That sent me down a much deeper rabbit hole.
By the end of it I had begun to re-evaluate Amazon::S3, its place in the parade of Perl S3 clients and, more pointedly, what an S3 client should do in the first place.
What exactly should an S3 client do?
That question matters because there are several ways for a Perl client to implement support for S3. Looking at how completely each one covers the S3 API turns out to be a poor measure of how useful it will be to an application. In fact, looking at the clients that do not provide full coverage - and what they offer instead - makes it much clearer what developers actually need from an S3 client.
Perl has accumulated several very different answers to that problem. Some favor breadth, some a smaller footprint, some a thinner interface, and some higher-level abstractions. Looking at those trade-offs turns out to be much more useful than simply asking which client implements the most S3 operations.
The API Is Not the Interface You’re Looking For
Take for instance multipart upload.
At the S3 API level you’ll find these operations:
A library that exposes those operations correctly can reasonably claim multipart upload support.
But a kit containing a dozen 2x4s and a box of nails is not a bench. Without instructions, it is just a pile of lumber and nails.
Your application wants to upload an object, not assemble an upload. So a more natural interface to those operations might look like this:
$bucket->upload_multipart_object(...);
This example is not unique. Many AWS services require an understanding of their intended usage that goes beyond merely hitting an endpoint with a GET or POST request.
A request to ListObjectsV2 returns a payload of information, but may require follow-up requests to retrieve the complete listing.
The model can describe GetObject. It cannot decide whether a client should download directly to a file, verify the returned checksum, retry an interrupted request, or simply hand the caller an HTTP response.
…and so on. Those decisions are encapsulated in each client library.
API completeness and library usefulness are clearly not the same thing.
Why a General-Purpose AWS SDK Is Usually the Wrong Answer
A general-purpose AWS SDK should faithfully expose the AWS service model. Perl has two that attempt to do exactly that.
But they are still the lumber without the instructions that tell you how to build your bench.
We could certainly use those SDKs in applications that need S3 support. But if the application is primarily trying to solve S3 problems, wouldn’t it be better to use a library that provides the higher-level abstractions that make those problems easier to solve?
That is what the other Perl S3 clients attempt to provide, each with its own goals, compromises, and trade-offs. Rather than approaching S3 through a general-purpose SDK interface, they speak directly to the S3 service and build their own abstractions around it.
S3 is one of the oldest AWS services. It is also something of an odd duck, having evolved over the years in response to changing client needs and advances in the underlying technology.
The result is a service with a collection of specialized behaviors: virtual-host versus path-style addressing, endpoint rules, multipart uploads, checksums, presigning, directory buckets, signing peculiarities, and other request and response behavior.
Even Botocore cannot treat S3 as simply another generated AWS service. It supplements the service metadata with S3-specific handlers and higher-level behavior.
So even the general-purpose SDK underlying Boto3 needs to know that S3 is special.
Unless a Perl SDK provides comparable S3-specific behavior, the application developer is left to assemble those higher-level operations themselves.
That is a strong argument for a purpose-built S3 client.
Perl’s General-Purpose SDKs
Paws was for many years the obvious Perl AWS SDK. Like Boto3, it uses AWS service metadata to generate classes that expose the underlying APIs through a common object model. Its own documentation still describes it as an attempt to provide an “always up-to-date SDK,” although the current release dates from January 2024.
Paws layers an object system over those APIs, but it does not provide much of the S3-specific plumbing an application needs. Its lack of currency also makes it harder to know whether that plumbing could be built reliably on top of the current AWS API surface.
Amazon::API takes the same metadata-driven approach with a much lighter object model. It uses Botocore metadata directly and can generate service and shape classes from the current metadata set, keeping the generated API surface aligned with Botocore as that metadata evolves.
Neither Paws nor Amazon::API is helping us build our bench.
Purpose-Built S3 Clients
What should our S3 client do?
- create this bucket
- put this file in the bucket
- get this object
- list this bucket
- delete these objects
- copy this object
- upload this large file
This is where purpose-built S3 clients begin to differentiate themselves.
Perl has several, and their differences expose the choices that can be made when designing a client around S3 rather than around the AWS service model.
Let’s take a look.
Net::Amazon::S3
Net::Amazon::S3 is the historical ancestor of much of this ecosystem, including Amazon::S3.
It is a mature and substantial S3 implementation with abstractions around buckets, objects, multipart uploads, authorization, vendor differences, and a broad range of S3 functionality.
That maturity includes a substantial dependency footprint. There is nothing inherently wrong with that, but you may not need everything Net::Amazon::S3 provides. Sometimes the architectural cost of a large library matters when your application only needs a small part of it.
Avoiding some of those costs was one of the reasons Amazon::S3 originally diverged from Net::Amazon::S3.
Amazon::S3::Lite
Amazon::S3::Lite chooses a much smaller target.
Its purpose is right there in the name: provide a lightweight client for common S3 operations.
- A Lambda function may need to retrieve an object, transform it, and write another one.
- A deployment script may only need to upload static assets.
- A small container may care much more about dependency weight than it does about supporting every bucket-management API AWS has added over the years.
For those applications, “Lite” is the requirement. Purpose driven.
Amazon::S3::Thin
Amazon::S3::Thin moves the abstraction boundary in another direction. It deliberately stays close to the HTTP transaction.
Think of it as extracting the S3 request layer while leaving most of the higher-level behavior to the application.
You’re on your own to assemble the bench…
And that may be exactly what you need.
AWS::S3
AWS::S3 provides another higher-level model, organizing access around bucket and file objects.
It is purpose-built around common S3 work rather than attempting to mirror every S3 API operation. Applications work with buckets and files as Perl objects, leaving much of the underlying request machinery to the library.
Again, that is a deliberate abstraction choice rather than an attempt at complete API coverage.
Amazon::S3
Amazon::S3 also provides higher-level abstractions around common bucket and object operations, but does not attempt to make the high-level interface cover every S3 API.
Instead, the distribution divides that work among three classes:
Amazon::S3- the control plane and orchestratorAmazon::S3::Bucket- the workhorse providing bucket and object managementAmazon::S3::BucketV2- fills the gap of missing APIs
Amazon::S3 2.1.0: A Better S3 Client?
Our survey of Perl S3 clients has shown us one thing: TIMTOWDI.
Which one is right for you? Not necessarily the one with the most complete coverage of the AWS API.
A better question is whether the client supports the way your application actually uses S3.
For example:
- a library with a small enough footprint for your deployment?
- upload files from the filesystem?
- upload objects already in memory?
- list buckets?
- list objects and object versions?
- create buckets?
- upload objects using a specific checksum algorithm?
- download objects and verify checksums?
- delete objects and object versions?
- delete buckets?
- perform multipart uploads without assembling the multipart workflow yourself?
- access less-common S3 APIs when the higher-level interface is not enough?
- work with alternate S3-compatible endpoints?
- provide useful error information when S3 rejects a request?
That is a much more useful measure of an S3 client than method count.
Amazon::S3 2.1.0 does not claim to be the only Perl client that can satisfy these kinds of requirements. Other clients make different choices, and some may be a better fit for particular applications.
What 2.1.0 does is move Amazon::S3 further toward covering both sides of the problem: convenient abstractions for common S3 work, and broader access to the service when those abstractions are not enough.
What Changed in 2.1.0
The PR that drove this work involved a bug that prevented an object from being downloaded when its ETag did not match the checksum calculated by the library.
That is what sent me down the rabbit hole and ultimately led to the most visible change in 2.1.0: modern checksum support.
But it did not stop there.
ETags != Checksums
For many years, S3 clients commonly treated an ETag as though it were an MD5 checksum.
That assumption no longer holds reliably.
Amazon::S3 2.1.0 therefore no longer interprets an ETag returned by GET as an MD5 digest. More importantly, it does not simply stop checking.
2.1.0 adds explicit support for the checksum algorithms commonly used by S3, including the current default used for new uploads.
Uploads now calculate and submit S3 checksums explicitly. The default algorithm is CRC64NVME, with local support for CRC32, CRC32C, MD5, SHA1, SHA256, and SHA512.
High-level multipart uploads carry the configured checksum algorithm through the multipart lifecycle.
Downloads request checksum metadata from S3 and verify supported
FULL_OBJECT checksums by default.
That verification is intentionally opportunistic.
If S3 does not return a checksum, the download succeeds.
If S3 returns a checksum using an algorithm the local installation does not support - currently only the XXHash algorithms are not implemented - the download succeeds.
Ranged responses are not incorrectly verified against a checksum that describes the complete object.
In other words, Amazon::S3 now verifies object integrity using metadata that S3 actually defines as a checksum.
That seems obvious when stated that way.
It was not what the old implementation did.
Multipart Uploads Should Be Multipart Uploads
The checksum work also forced a closer examination of multipart uploads.
Here the distinction between API completeness and a useful client becomes concrete.
Amazon::S3 continues to expose the low-level multipart operations for callers that want to manage the lifecycle themselves. Those methods do not silently opt the caller into new checksum behavior.
The high-level upload_multipart_object() method is different.
It owns the multipart lifecycle, so it can also own the checksum state needed to perform that operation correctly.
When Amazon::S3 initiates the multipart upload, uploads the parts, and completes the upload, 2.1.0 carries the selected checksum algorithm and the relevant per-part checksums through that process.
That is exactly the kind of behavior that cannot be inferred merely by counting API methods.
The individual operations are the protocol.
upload_multipart_object() is the library.
Better Error Exposure
Amazon::S3 has always provided access to error information.
The problem was that callers sometimes had to know to ask for it.
Some methods returned a failure value and left the details behind in the Amazon::S3 object. If the caller did not immediately inspect the stored error code and message, a failed operation could look remarkably like nothing had happened.
That is not especially helpful when S3 has already told us exactly what went wrong.
S3 error responses often include a service error code and message in
the response body. An HTTP status such as 400, 403, or 404 tells
you the broad class of failure, but not necessarily why S3 rejected the
request.
Amazon::S3 2.1.0 does a better job of extracting and retaining that S3 error information, and methods that report request failures can include the HTTP status together with the S3 error code and message.
The caller should not have to perform a second investigation to learn what the service already said.
BucketV2 Became a Real Interface
2.1.0 also tightened the boundary between Amazon::S3::Bucket and
Amazon::S3::BucketV2.
BucketV2 is where Amazon::S3 exposes the broader, AWS-shaped S3 API surface when the higher-level Bucket interface does not provide a convenience method.
That distinction existed conceptually, but the implementation had grown a little blurry.
Focused tests around the dynamically generated BucketV2 methods found
both a request-generation bug and a namespace problem. Generated methods
that belonged to BucketV2 were historically installed in
Amazon::S3::Bucket.
Both issues are fixed in 2.1.0.
The result is simple: if an application wants the broader S3 API surface, it asks for a BucketV2 object, and the implementation now behaves accordingly.
Documentation That Describes the Architecture
The documentation for Amazon::S3, Amazon::S3::Bucket, and
Amazon::S3::BucketV2 has been substantially rewritten.
That was not incidental cleanup.
If Bucket and BucketV2 serve different purposes, the documentation needs to make that distinction clear.
Amazon::S3 now carries the conceptual material: authentication,
checksums, listing behavior, multipart uploads, and the relationship
between the two bucket interfaces.
Amazon::S3::Bucket focuses on the higher-level operations developers
normally use.
Amazon::S3::BucketV2 documents the additional AWS-shaped API surface.
The documentation now reflects the architecture instead of making the reader infer it.
Other Changes
2.1.0 also replaces the old Autoconf/Automake build machinery with the simpler build system I now use for my CPAN distributions.
Testing has expanded along with the implementation. The final LocalStack suite for 2.1.0 runs 155 tests across 10 test files, including focused coverage for checksums, multipart uploads, and BucketV2 request generation.
Where Amazon::S3 Goes Next
2.1.0 does not make Amazon::S3 complete, nor is completeness the only goal.
There are still S3 APIs that belong in BucketV2 and higher-level
operations that can make common work easier. Uploads could accept more
kinds of input. An empty_bucket() operation would eliminate another
piece of repetitive application code. I am also experimenting with a
command-line interface for common S3 operations.
Endpoint handling deserves another look as well.
Amazon::API has taught me a great deal about the value of deriving AWS behavior from Botocore metadata. That makes sense when you are trying to support hundreds of AWS services.
Amazon::S3 has only one service to understand.
For S3, it may therefore make more sense to continue encoding the documented behavior directly rather than turn Amazon::S3 into another Botocore interpreter.
That is work for another release.
On Being an S3 Client
Amazon::S3 2.1.0 started with a bug report about ETags.
It ended up forcing a much larger question about what this library is supposed to be.
Amazon::S3 is not an AWS SDK. It is not trying to be the smallest S3 client or merely expose every operation AWS documents.
It is trying to make S3 useful to Perl applications.
That means providing higher-level operations when the application needs a bench instead of lumber, while still exposing the underlying S3 API when the application needs to build something else.
2.1.0 is a significant step in that direction.
Whether it is a better S3 client is ultimately for its users to decide.
Some Useful Links
Previous post: Reflecting on Mirrors - Part II
BigfootInMouth
A blog by Rob Lauer.
 www.linkedin.com/in/rob-lauer-1590513
Search
Recent Posts
- Amazon::S3 v2.1.0 - On Being an S3 Client
- Reflecting on Mirrors - Part II
- Reflecting on Mirrors - Part I
- Announcing Amazon::API 2.8.0 - A Lightweight AWS API for Perl
- Phoenix Rising: Why Perl’s Unix Roots Matter More Than Ever
- Abstract Algebra, The Simpsons, and Malcom In in the Middle
- Python 3.15: (Or, How Python is Slowly Becoming Perl)
- Idempotent AWS Resource Creation - with tools you have laying around the house
- Six Ways to Use AI Without Giving Up the Keys
- Stop Writing Release Notes: Accelerate with AI